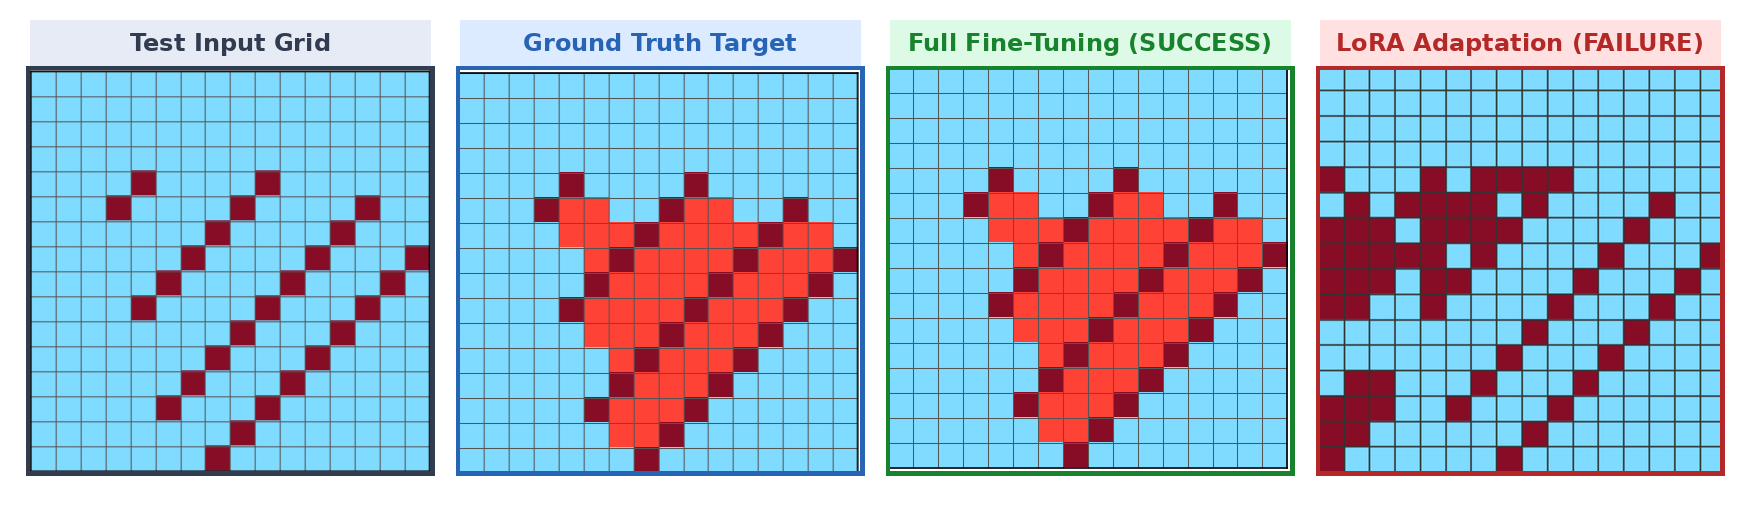
Full Fine-Tuning vs. LoRA for Test-Time Training on ARC-AGI-2
The Tiny Recursive Model (TRM, 7M parameters) learns a separate embedding for every puzzle it is trained on, so it has never been tested on a task it has truly not seen. I pre-trained a TRM with the 120 ARC-AGI-2 evaluation tasks held out, then adapted it to those unseen tasks at test time, comparing full fine-tuning with LoRA.
- 4.07%pass@2 on held-out ARC-AGI-2 tasks
- ~70×lower training loss than LoRA
- 48A100 GPU-hours in the sweep
For reference, the original TRM scores 7.80%, but it saw these tasks during pre-training and was pre-trained 5× longer.